The landscape of Artificial Intelligence has shifted toward high-efficiency architectures. For software engineers, DevOps teams, and tech startups building AI-powered applications, choosing between the ChatGPT API (OpenAI) and the DeepSeek API is no longer just a benchmark comparison—it is a critical infrastructure financial decision. While OpenAI’s flagship models remain an industry standard for multi-modal tasks, DeepSeek has disrupted traditional market economics by offering comparable performance at a fraction of the operational cost. This deep dive evaluates the technical infrastructure, raw token pricing, and cost-optimization strategies—such as prompt caching —to help you scale production applications efficiently. Core Architecture and API Infrastructure Efficiency To understand why API pricing differs so dramatically between t...
Most cost reductions come from three structural changes, not from prompt micro-tuning. Done in order, they typically remove half to two thirds of a bill without a measurable quality drop. Step 1: Find where the money actually goes Log cost per request alongside the feature, endpoint and user tier that produced it. In most applications a small share of requests dominates spend: long-context calls, agent loops that iterate, and retries. Optimising a high-volume cheap endpoint feels productive and moves the total by almost nothing. Step 2: Route by difficulty Send every request to the cheapest model that reliably passes evaluation for that task class, and reserve the flagship model for requests that genuinely need it. The spread makes this worthwhile: $0.10 on GPT-6 Luna against $10.00 on Claude Fable 5.1, a 100x difference on input. A router needs a cheap classifier — a few hundred input tokens on a small model — and a fallback path when the small model's confidence is low. Start w...
Prompt caching lets a provider reuse work it has already done. When you send a request whose opening tokens exactly match a prefix the provider has processed recently, it skips that portion and bills the reused tokens at a cache-read rate instead of the full input rate. For applications with long system prompts, fixed schemas or repeated document context, this is the largest single lever on API spend. How much cheaper is a cache read The discount differs sharply by provider. The table below shows the cache-read price against the fresh input price for every model in the dataset that publishes one. Model Input Cached input Discount Cache write DeepSeek V4.1 Flash $0.30 $0.0060 98% — Claude Fable 5.1 $10.00 $0.25 97.5% $12.50 DeepSeek V4 Pro $1.32 $0.04 96.7% — GPT-6.1 Sol $2.00 $0.10 95% $2.50 GPT-6 Astra $10.00 $1.00 90% $12.50 GPT-6 Sol $2.00 $0.20 90% $2.50 GPT-6 Luna $0.10 $0.01 90% $0.13 GPT-5.6 Sol $4.00 $0.40 90% $5.00 GPT-5.6 Terra $2.00 $0.20 90% $2.50 GPT-5.6 Luna...
Output tokens usually cost 3x to 5x more than input. See the real ratios for 28 models and how each one changes your monthly bill.
Onsp
Every provider charges less for input than for output, and the size of that gap varies far more than most teams expect. Understanding why it exists, and how wide it is, changes which model you should pick for a given workload.
Why output costs more
Input tokens are processed in parallel. The whole prompt can be pushed through the model at once, which is efficient on modern accelerators. Output tokens are generated one at a time, each requiring a full forward pass, with the result appended and fed back in. Generating a thousand tokens takes a thousand sequential steps; reading a thousand tokens does not.
That asymmetry is the reason output pricing is higher, and it is also why output price is the number to optimise when your product generates long responses.
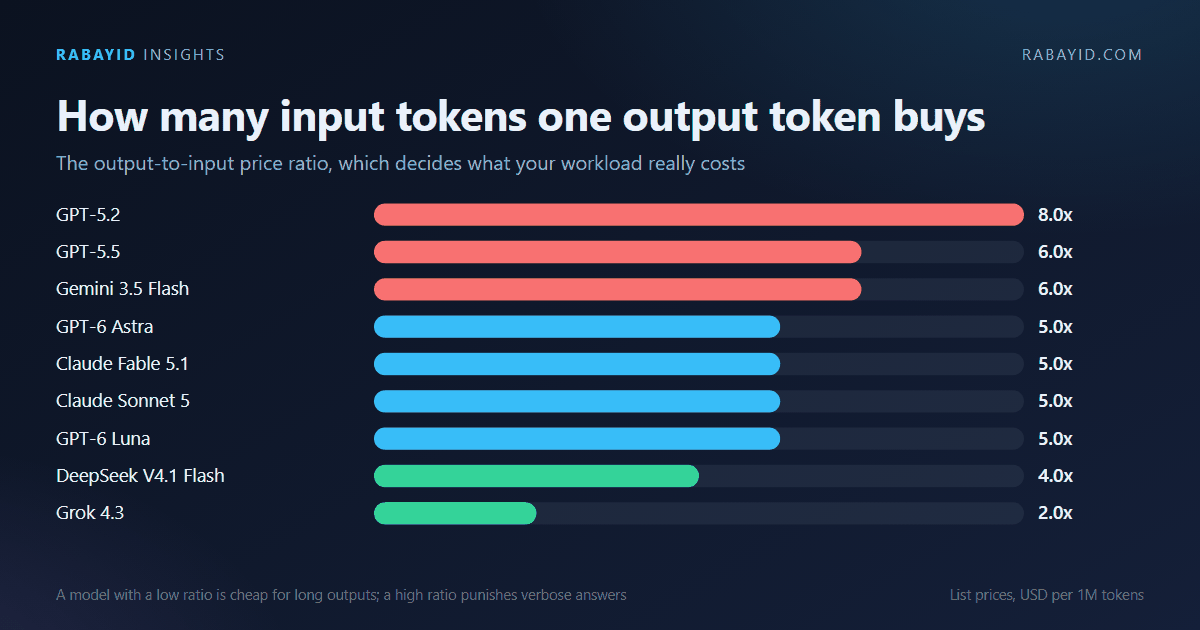
The multiple varies from 2x to 6x
Model
Input
Output
Multiple
Grok 4.3
$1.25
$2.50
2.0x
Grok 4.6
$2.00
$6.00
3.0x
DeepSeek V4 Pro
$1.32
$3.96
3.0x
GPT-4.1
$2.00
$8.00
4.0x
DeepSeek V4.1 Flash
$0.30
$1.20
4.0x
GPT-6 Astra
$10.00
$50.00
5.0x
GPT-6.1 Sol
$2.00
$10.00
5.0x
GPT-6 Sol
$2.00
$10.00
5.0x
GPT-6 Luna
$0.10
$0.50
5.0x
GPT-5.6 Sol
$4.00
$20.00
5.0x
Claude Fable 5.1
$10.00
$50.00
5.0x
Claude Opus 5
$5.00
$25.00
5.0x
Claude Sonnet 5
$2.00
$10.00
5.0x
Claude Sonnet 4.6
$3.00
$15.00
5.0x
Claude Haiku 4.5
$1.00
$5.00
5.0x
Gemini 3.8 Flash
$0.75
$3.75
5.0x
Gemini 3.7 Flash
$0.75
$3.75
5.0x
GPT-5.6 Luna
$0.20
$1.20
6.0x
GPT-5.6 Terra
$2.00
$12.00
6.0x
GPT-5.5
$5.00
$30.00
6.0x
GPT-5.4
$2.50
$15.00
6.0x
GPT-5.4 mini
$0.75
$4.50
6.0x
Gemini 3.5 Flash
$1.50
$9.00
6.0x
Gemini 3.1 Pro (Preview)
$2.00
$12.00
6.0x
GPT-5.4 nano
$0.20
$1.25
6.3x
GPT-5.2
$1.75
$14.00
8.0x
Gemini 2.5 Pro
$1.25
$10.00
8.0x
Gemini 3.5 Flash-Lite
$0.30
$2.50
8.3x
The lowest multiple in this dataset is Grok 4.3 at 2.0x. The highest is Gemini 3.5 Flash-Lite at 8.3x. For a generation-heavy workload that difference matters more than the headline input rate.
Choosing a model from your ratio
Compute your own input-to-output ratio from production logs, then price candidates as (in_ratio × in_price + out_ratio × out_price) / (in_ratio + out_ratio).
Workload shape
Typical ratio
What matters
Classification, extraction
20:1 input-heavy
Input price and cache rate
RAG question answering
10:1 input-heavy
Input price, cache rate, context window
Chat
3:1 balanced
Blended price
Code generation
1:5 output-heavy
Output price and output multiple
Long-form writing
1:10 output-heavy
Output price, max output cap
Practical levers on the output line
Set a max output token cap per endpoint. Unbounded generation is the single most common cause of an unexpected output bill, because a model that decides to elaborate will elaborate.
Instruct format explicitly. "Return only the JSON object, no explanation" removes the preamble that otherwise lands on the output line. Use structured output modes where offered, since constrained decoding can also reduce wasted tokens.
Watch reasoning overhead. On reasoning models, internal tokens are billed at the output rate even though you never see them. Lowering reasoning effort on straightforward tasks cuts the output line directly.
Where caching fits
Caching only applies to input. There is no mechanism to cache output, so a cache can never reduce the output portion of a bill. If output dominates your spend, caching will disappoint you, and the right move is model selection plus output caps instead.
Price your actual ratio in the calculator before choosing — a model that looks expensive per token can be the cheapest for your shape of traffic.
It seems there is something wrong with your internet connection. Please connect to the internet and start browsing again.
AdBlock Detected!
We have detected that you are using adblocking plugin in your browser. The revenue we earn by the advertisements is used to manage this website, we request you to whitelist our website in your adblocking plugin.
Site is Blocked
Sorry! This site is not available in your country.