The landscape of Artificial Intelligence has shifted toward high-efficiency architectures. For software engineers, DevOps teams, and tech startups building AI-powered applications, choosing between the ChatGPT API (OpenAI) and the DeepSeek API is no longer just a benchmark comparison—it is a critical infrastructure financial decision. While OpenAI’s flagship models remain an industry standard for multi-modal tasks, DeepSeek has disrupted traditional market economics by offering comparable performance at a fraction of the operational cost. This deep dive evaluates the technical infrastructure, raw token pricing, and cost-optimization strategies—such as prompt caching —to help you scale production applications efficiently. Core Architecture and API Infrastructure Efficiency To understand why API pricing differs so dramatically between t...
Most cost reductions come from three structural changes, not from prompt micro-tuning. Done in order, they typically remove half to two thirds of a bill without a measurable quality drop. Step 1: Find where the money actually goes Log cost per request alongside the feature, endpoint and user tier that produced it. In most applications a small share of requests dominates spend: long-context calls, agent loops that iterate, and retries. Optimising a high-volume cheap endpoint feels productive and moves the total by almost nothing. Step 2: Route by difficulty Send every request to the cheapest model that reliably passes evaluation for that task class, and reserve the flagship model for requests that genuinely need it. The spread makes this worthwhile: $0.10 on GPT-6 Luna against $10.00 on Claude Fable 5.1, a 100x difference on input. A router needs a cheap classifier — a few hundred input tokens on a small model — and a fallback path when the small model's confidence is low. Start w...
Prompt caching lets a provider reuse work it has already done. When you send a request whose opening tokens exactly match a prefix the provider has processed recently, it skips that portion and bills the reused tokens at a cache-read rate instead of the full input rate. For applications with long system prompts, fixed schemas or repeated document context, this is the largest single lever on API spend. How much cheaper is a cache read The discount differs sharply by provider. The table below shows the cache-read price against the fresh input price for every model in the dataset that publishes one. Model Input Cached input Discount Cache write DeepSeek V4.1 Flash $0.30 $0.0060 98% — Claude Fable 5.1 $10.00 $0.25 97.5% $12.50 DeepSeek V4 Pro $1.32 $0.04 96.7% — GPT-6.1 Sol $2.00 $0.10 95% $2.50 GPT-6 Astra $10.00 $1.00 90% $12.50 GPT-6 Sol $2.00 $0.20 90% $2.50 GPT-6 Luna $0.10 $0.01 90% $0.13 GPT-5.6 Sol $4.00 $0.40 90% $5.00 GPT-5.6 Terra $2.00 $0.20 90% $2.50 GPT-5.6 Luna...
A one-million-token context window is not a one-million-token price. Every major provider sells the window at one rate and then charges a different, h
Onsp
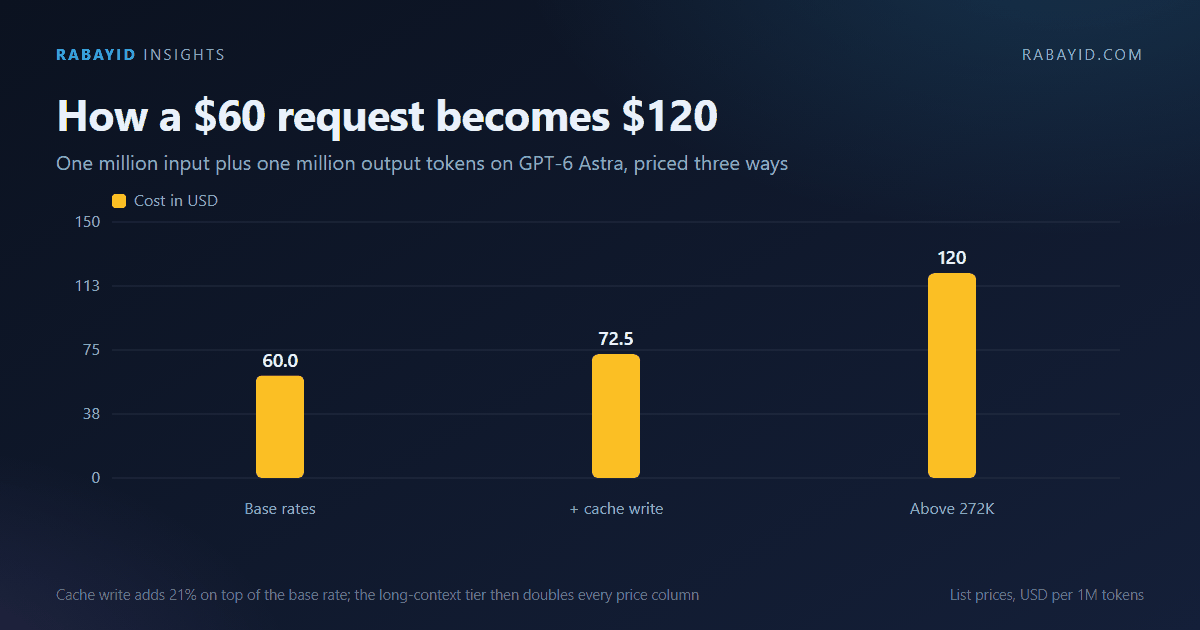
A one-million-token context window is not a one-million-token price. Every major provider sells the window at one rate and then charges a different, higher rate once a prompt crosses a threshold — 200,000 tokens at Google and xAI, 272,000 at OpenAI. Above the line, the entire request bills at the higher rate, not just the excess tokens.
That distinction is where budgets break. A team that reads "1M context" and assumes a flat rate plans for $2.00 on a million-token call and receives a $4.00 invoice. Worse, the cliff is invisible in most cost calculators, because they multiply tokens by a single rate. This article maps every threshold in the dataset and works out when paying the surcharge is rational.
Long-context tiers are the least visible line item in an LLM bill.
Every threshold, October 2026
Model
Window
Tier starts
Input above tier
Output above tier
Gemini 3.8 / 3.7 Flash
1M
200K
$1.50
$7.50
Gemini 3.1 Pro
1M
200K
$4.00
$18.00
Gemini 2.5 Pro
1M
200K
$2.50
$15.00
Grok 4.3
1M
200K
$2.50
$5.00
Grok 4.6
500K
200K
$4.00
$12.00
GPT-6 Astra
1.05M
272K
$20.00
$75.00
GPT-6 Sol / 6.1 Sol
1.05M
272K
$4.00
$15.00
GPT-6 Luna
1.05M
272K
$0.20
$0.75
GPT-5.6 family
1.05M
272K
2× base
1.5× base
Claude Sonnet 5 / Opus 5 / Fable 5.1
1M
None
—
—
DeepSeek V4.1 Flash
1.1M
None
—
—
DeepSeek V4 Pro
1M
None
—
—
What a million-token prompt actually costs
One call, one million input tokens, no output. This is the number that matters when someone says "we'll just put the whole codebase in the prompt".
Model
Cost for 1M input
Effective rate / 1K
Tier applies?
DeepSeek V4.1 Flash
$0.30
$0.0003
No
Gemini 3.8 Flash
$1.50
$0.0015
Yes (2×)
Claude Sonnet 5
$2.00
$0.0020
No
Grok 4.3
$2.50
$0.0025
Yes (2×)
GPT-6 Sol
$4.00
$0.0040
Yes (2×)
Gemini 3.1 Pro
$4.00
$0.0040
Yes (2×)
Grok 4.6
$4.00 (capped at 500K)
—
Yes (2×)
GPT-6 Astra
$20.00
$0.0200
Yes (2×)
The spread is 67× between DeepSeek and GPT-6 Astra for the same nominal one-million-token window. Model choice dominates every optimisation technique at this length — compression included.
Why crossing the line is worse than it looks
The surcharge applies to the whole request. Take GPT-6 Sol: below 272K, input bills at $2.00 per million; above it, $4.00. A 400,000-token prompt therefore costs $1.60, not the $0.80 a naive multiplication suggests.
Now compress it to 250,000 tokens. You removed 37.5% of the tokens and saved 69% of the cost:
Prompt
Tokens
Rate
Input cost
Uncompressed
400,000
$4.00 (tier)
$1.60
Compressed
250,000
$2.00 (base)
$0.50
Saving
−37.5%
—
−69%
This is the highest-leverage optimisation in the entire field, and it is why "just add more context" is usually the most expensive way to improve an answer. The goal is not to fit the window; it is to stay below the threshold.
Three ways to compress without losing the answer
1. Rerank before you retrieve. Most RAG pipelines retrieve 50 documents and use all 50. A cross-encoder reranker that keeps the best 8 usually preserves answer quality while cutting tokens by 80%. The cost of the reranker is a fraction of the tokens it saves.
2. Summarise the middle, keep the edges. Models attend most reliably to the start and end of a long context. Compressing the middle third into a structured summary — entities, decisions, numbers — preserves most of the signal at a third of the length.
3. Extract, then reason. Instead of sending 300 pages and asking a question, run a cheap extraction pass with GPT-6 Luna that pulls only the fields the question needs, then send 2,000 tokens to the expensive model. Two calls, a fraction of the cost.
When paying the surcharge is correct
Compression has a failure mode: it removes the sentence that mattered. Four workloads justify the full window:
Legal and contract review — the missing clause is the point of the review.
Whole-repository analysis — cross-file dependencies cannot be summarised away.
Long transcripts — a summary of a two-hour call loses exactly the details being audited.
One-shot synthesis — where chunking would produce five inconsistent answers instead of one.
In those cases the comparison is not "long context versus cheap" but "long context versus a human reading it", and the surcharge is trivial.
The cheapest long-context model is not the obvious one
Claude Sonnet 5 has no surcharge and costs $2.00 for a million-token prompt — half of GPT-6 Sol's $4.00 despite identical sticker rates. DeepSeek V4.1 Flash costs $0.30 and offers 1.1M tokens flat, which is 13× cheaper than GPT-6 Sol at the same length.
If your workload genuinely needs very long prompts, the model shortlist is DeepSeek first on price, Claude second, and everything else a distant third. If your workload merely drifted above 272K by accident, the answer is compression, not a different provider.
FAQ
What is a long-context surcharge?
A higher per-token rate that applies to the entire request once the prompt exceeds a provider threshold — 200,000 tokens at Google and xAI, 272,000 at OpenAI. Anthropic and DeepSeek do not apply one.
Does the surcharge apply only to the extra tokens?
No. The whole request moves to the higher rate. A 300,000-token prompt on GPT-6 Sol bills all 300,000 tokens at $4.00, not 272,000 at $2.00 and 28,000 at $4.00.
Which model is cheapest for a 1M-token prompt?
DeepSeek V4.1 Flash at $0.30, followed by Gemini 3.8 Flash at $1.50 and Claude Sonnet 5 at $2.00.
Is a larger context window always better?
No. Above the threshold, a larger window costs twice as much per token, and accuracy on very long inputs is not guaranteed. Compression below the threshold is usually the cheaper and more accurate option.
It seems there is something wrong with your internet connection. Please connect to the internet and start browsing again.
AdBlock Detected!
We have detected that you are using adblocking plugin in your browser. The revenue we earn by the advertisements is used to manage this website, we request you to whitelist our website in your adblocking plugin.
Site is Blocked
Sorry! This site is not available in your country.