The landscape of Artificial Intelligence has shifted toward high-efficiency architectures. For software engineers, DevOps teams, and tech startups building AI-powered applications, choosing between the ChatGPT API (OpenAI) and the DeepSeek API is no longer just a benchmark comparison—it is a critical infrastructure financial decision. While OpenAI’s flagship models remain an industry standard for multi-modal tasks, DeepSeek has disrupted traditional market economics by offering comparable performance at a fraction of the operational cost. This deep dive evaluates the technical infrastructure, raw token pricing, and cost-optimization strategies—such as prompt caching —to help you scale production applications efficiently. Core Architecture and API Infrastructure Efficiency To understand why API pricing differs so dramatically between t...
Most cost reductions come from three structural changes, not from prompt micro-tuning. Done in order, they typically remove half to two thirds of a bill without a measurable quality drop. Step 1: Find where the money actually goes Log cost per request alongside the feature, endpoint and user tier that produced it. In most applications a small share of requests dominates spend: long-context calls, agent loops that iterate, and retries. Optimising a high-volume cheap endpoint feels productive and moves the total by almost nothing. Step 2: Route by difficulty Send every request to the cheapest model that reliably passes evaluation for that task class, and reserve the flagship model for requests that genuinely need it. The spread makes this worthwhile: $0.10 on GPT-6 Luna against $10.00 on Claude Fable 5.1, a 100x difference on input. A router needs a cheap classifier — a few hundred input tokens on a small model — and a fallback path when the small model's confidence is low. Start w...
Prompt caching lets a provider reuse work it has already done. When you send a request whose opening tokens exactly match a prefix the provider has processed recently, it skips that portion and bills the reused tokens at a cache-read rate instead of the full input rate. For applications with long system prompts, fixed schemas or repeated document context, this is the largest single lever on API spend. How much cheaper is a cache read The discount differs sharply by provider. The table below shows the cache-read price against the fresh input price for every model in the dataset that publishes one. Model Input Cached input Discount Cache write DeepSeek V4.1 Flash $0.30 $0.0060 98% — Claude Fable 5.1 $10.00 $0.25 97.5% $12.50 DeepSeek V4 Pro $1.32 $0.04 96.7% — GPT-6.1 Sol $2.00 $0.10 95% $2.50 GPT-6 Astra $10.00 $1.00 90% $12.50 GPT-6 Sol $2.00 $0.20 90% $2.50 GPT-6 Luna $0.10 $0.01 90% $0.13 GPT-5.6 Sol $4.00 $0.40 90% $5.00 GPT-5.6 Terra $2.00 $0.20 90% $2.50 GPT-5.6 Luna...
OpenAI's 2026 price list is not one price list. It is thirteen tiers spread across a 100× range: GPT-6 Astra bills $10 per million input tokens, GPT-6
Onsp
OpenAI's 2026 price list is not one price list. It is thirteen tiers spread across a 100× range: GPT-6 Astra bills $10 per million input tokens, GPT-6 Luna bills $0.10 for the same million. Both are current, both are supported, and both appear in the same documentation page. The gap between them is not a rounding error — it is the difference between a $70 bill and a $0.70 bill for identical work.
This guide does three things the pricing page does not. It converts sticker rates into the cost of a workload you can recognise, it explains the two rules that quietly double or halve a bill (caching and the long-context threshold), and it names the tier you should actually pick for each job.
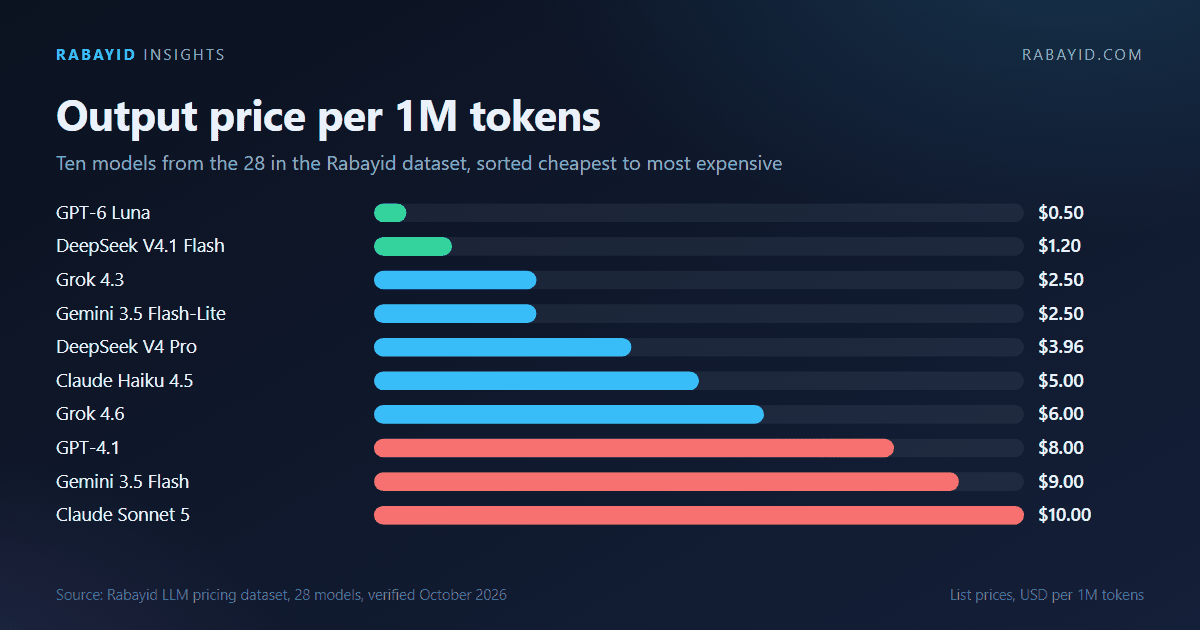
API cost per 1M tokens across major providers, October 2026.
Every OpenAI rate, October 2026
All figures are USD per 1,000,000 tokens. "Cached" is the price of a token served from a prompt cache; "write" is the one-off charge for storing that prefix.
Model
Input
Cached
Write
Output
Context
Batch
GPT-6 Astra
$10.00
$1.00
$12.50
$50.00
1.05M
Yes
GPT-6.1 Sol
$2.00
$0.10
$2.50
$10.00
1.05M
Yes
GPT-6 Sol
$2.00
$0.20
$2.50
$10.00
1.05M
Yes
GPT-5.6 Terra
$2.00
$0.20
$2.50
$12.00
1.05M
Yes
GPT-5.6 Sol (promo)
$4.00
$0.40
$5.00
$20.00
1.05M
Yes
GPT-6 Luna
$0.10
$0.01
$0.125
$0.50
1.05M
Yes
GPT-5.6 Luna
$0.20
$0.02
$0.25
$1.20
1.05M
Yes
GPT-5.4 mini
$0.75
$0.075
—
$4.50
400K
Yes
GPT-5.4 nano
$0.20
$0.02
—
$1.25
400K
Yes
GPT-5.2
$1.75
$0.175
—
$14.00
400K
Yes
GPT-5.4
$2.50
$0.25
—
$15.00
1.05M
Yes
GPT-5.5
$5.00
$0.50
—
$30.00
1.05M
Yes
GPT-4.1
$2.00
$0.50
—
$8.00
1.05M
Yes
Rates verified October 2026. GPT-5.6 Sol is promotional and holds at least through 21 November 2026 (it was $5/$30). GPT-5.6 Terra was cut in price on 30 July 2026. Always confirm on OpenAI's pricing page before committing a budget.
What 1,000 support requests actually cost
A sticker rate is not a bill. Take a realistic support workload — 1,000 conversations, each with a 4,000-token prompt (system message, retrieved help-centre articles, conversation history) and a 600-token answer. That is 4 million input tokens and 600,000 output tokens.
Model
Input cost
Output cost
Total
vs cheapest
GPT-6 Astra
$40.00
$30.00
$70.00
100×
GPT-5.5
$20.00
$18.00
$38.00
54×
GPT-5.6 Sol
$16.00
$12.00
$28.00
40×
GPT-5.4
$10.00
$9.00
$19.00
27×
GPT-5.2
$7.00
$8.40
$15.40
22×
GPT-5.6 Terra
$8.00
$7.20
$15.20
22×
GPT-6.1 Sol
$8.00
$6.00
$14.00
20×
GPT-6 Sol
$8.00
$6.00
$14.00
20×
GPT-4.1
$8.00
$4.80
$12.80
18×
GPT-5.4 mini
$3.00
$2.70
$5.70
8×
GPT-5.4 nano
$0.80
$0.75
$1.55
2.2×
GPT-5.6 Luna
$0.80
$0.72
$1.52
2.2×
GPT-6 Luna
$0.40
$0.30
$0.70
1×
Two things stand out. First, output is not a minor line item: on GPT-6 Astra it is 43% of the bill despite being 13% of the tokens. Second, GPT-4.1 is still cheaper than GPT-6 Sol for this shape of work — $8 of output beats $10 — which is why retired models keep running in production long after their replacement ships.
The caching rule that decides your real rate
OpenAI sells three input prices, not one. On every GPT-6 tier, writing a prefix to cache costs 1.25× the base input rate, and reading it back costs 5–10% of that rate. On GPT-6.1 Sol the read is $0.10 against a $2.00 base: 5%. On GPT-6 Sol it is $0.20: 10%. Same headline price, double the cache cost.
That makes the break-even arithmetic simple. A cached prefix pays for itself once the write premium is recovered:
For GPT-6 Sol that is 2.50 ÷ (2.00 − 0.20) = 1.39. In plain terms: cache a prefix you reuse twice and you are already ahead. For GPT-6.1 Sol it is 2.50 ÷ 1.90 = 1.32. The two Sol models are the same price until your prompt has a stable prefix — then 6.1 is meaningfully cheaper.
Support bots, RAG pipelines and coding agents all carry a stable prefix: system instructions, tool schemas, retrieved documents that change slowly. Caching a 45,000-token retrieval block on a 50,000-token prompt cuts the input side of the bill by roughly 90% after the first call. The full mechanics are in prompt caching explained, and the payback maths in caching as an investment.
The 272,000-token cliff
Every GPT-6 model advertises a 1.05M-token context window. The price list is less generous: above 272,000 input tokens, rates move to a long-context tier. GPT-6 Sol goes from $2/$10 to $4/$15; GPT-6 Astra from $10/$50 to $20/$75; GPT-6 Luna from $0.10/$0.50 to $0.20/$0.75.
The practical consequence is that the last 780,000 tokens of the window cost twice as much as the first 272,000. A single 1M-token call on GPT-6 Sol costs $4.00 in input alone — twice the $2.00 the headline rate suggests. If your retrieval layer can compress 400,000 tokens to 250,000, you do not save 37% of the input cost, you save 50% of it, because you drop back under the threshold. That is the single highest-leverage optimisation available on OpenAI's stack, and it is covered in long-context cost explained.
Batch: the 50% discount nobody enables
Every tier above supports the Batch API, which halves both input and output rates for jobs that can wait up to 24 hours. The nightly-job example — 10,000 requests of 10,000 input and 2,000 output tokens — costs $400 on GPT-6 Sol at list price and $200 in batch mode. Run that every night for a year and the difference is $73,000.
Batch is not a niche feature. Classification backfills, embedding refreshes, report generation, evaluation runs and data labelling all fit the 24-hour window. The constraint is latency, not capability: anything a user is waiting for cannot use it.
Which tier for which job
Routing, tagging, extraction, moderation — GPT-6 Luna at $0.10/$0.50. Nothing else in the catalogue comes close on price per correct label, and its 1.05M context means you rarely need chunking.
Product workhorse (chat, agents, coding) — GPT-6.1 Sol. Identical sticker price to GPT-6 Sol with half the cached-input rate, so it wins the moment you cache.
Output-heavy generation — GPT-4.1 at $8 output remains cheaper than every GPT-6 tier except Luna. If quality holds for your task, it is the value pick.
High-stakes reasoning — GPT-6 Astra at $10/$50. Reserve it for work where a wrong answer costs more than the token bill.
Legacy deployments — GPT-5.4 mini and nano at 400K context are still the cheapest way to serve a small-context product.
Three mistakes that inflate an OpenAI bill
1. Paying for output you discard. Asking for a JSON object and then parsing the first field still bills every token the model emits. Constrain output length explicitly; output is 5× the input rate on every GPT-6 tier.
2. Sending the same system prompt 10,000 times uncached. A 2,000-token system prompt costs $0.004 per call at GPT-6 Sol rates — $40 per 10,000 calls. Cached, it costs $0.40 plus a one-off $0.005 write.
3. Crossing 272K tokens by accident. Retrieval layers that "just add one more document" can push a prompt over the threshold and double the rate for the entire call. Cap retrieved context in code, not in the prompt.
FAQ
How much does GPT-6 cost per million tokens?
GPT-6 Astra: $10 input / $50 output. GPT-6.1 Sol and GPT-6 Sol: $2 / $10. GPT-6 Luna: $0.10 / $0.50. Cached input ranges from $0.01 to $1.00 depending on tier.
Is GPT-6.1 Sol cheaper than GPT-6 Sol?
At list price they are identical: $2 input and $10 output. The difference is cached input — $0.10 versus $0.20 per million. For any workload with a reusable prefix, GPT-6.1 Sol is roughly 5–7% cheaper overall; for one-shot prompts they cost the same.
Does the Batch API stack with prompt caching?
Both discounts apply to their own token class, but the safe budgeting assumption is the simpler one: batch halves the list rate. Build your forecast on that, then treat any cache saving as upside.
What happens above 272,000 tokens?
The whole request moves to the long-context tier: GPT-6 Sol bills $4 input and $15 output instead of $2 and $10. Compression below the threshold is usually cheaper than paying the tier.
It seems there is something wrong with your internet connection. Please connect to the internet and start browsing again.
AdBlock Detected!
We have detected that you are using adblocking plugin in your browser. The revenue we earn by the advertisements is used to manage this website, we request you to whitelist our website in your adblocking plugin.
Site is Blocked
Sorry! This site is not available in your country.